

问题原文
原帖链接 · Mark · CC BY-SA 3.0
I found a strange search result for a resource blocked by robots.txt.
Why ist there the Chinese (guessed) text followed by the text Hello nighthawk!. Is this an esteregg of Google?
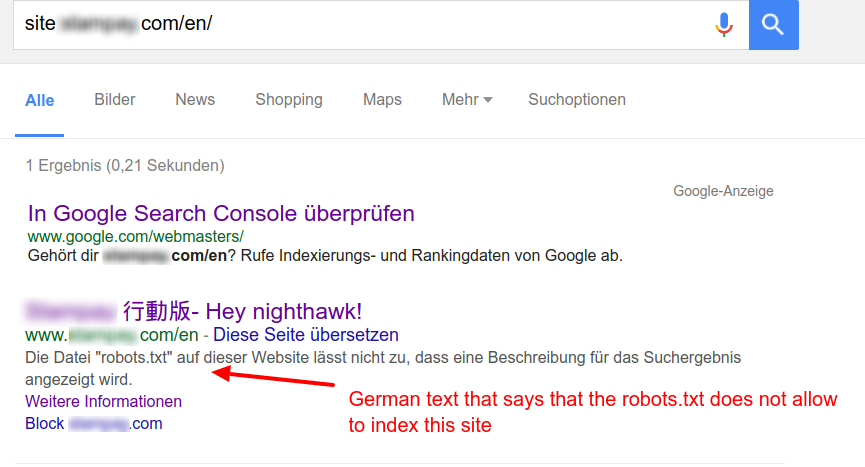
Yesterday I tried to remove the URL from google with Webmaster Tools.
There was no Hello Nighthawk!, only the 'blocked by robots.txt' message. The issue was reported by a co-woker.
This is the content of the robots.txt:
User-agent: *
Disallow: /en
The domains gets redirected in the following way:
www.domain.com/en -> (301) https://domain.com/en
The page https://domain.com/en show the normal page with the correct title of the page.
The title of domain.com/en does not contain any of the words.
I have searched the whole project to find the word 'nighthawk'. It is not included. And we never had any Chinese translations.
已采纳解答
原帖链接 · Stephen Ostermiller · CC BY-SA 3.0
Google includes uncrawlable pages in the index when they are linked from other sites.
That means that a link to the website like<a href="domain.com/en">[CHINESE] - Hey nighthawk</a> can show up in the search results.
Some have suggested that such occurrences are temporary. They aren't always. Google indexes uncrawlable pages because sometimes important pages are blocked by robots.txt. Matt Cutts explains:
You might wonder why Google will sometimes return an uncrawled url reference, even if Googlebot was forbidden from crawling that url by a robots.txt file. There’s a pretty good reason for that: back when I started at Google in 2000, several useful websites (eBay, the New York Times, the California DMV) had robots.txt files that forbade any page fetches whatsoever. Now I ask you, what are we supposed to return as a search result when someone does the query [california dmv]? We’d look pretty sad if we didn’t return www.dmv.ca.gov as the first result. But remember: we weren’t allowed to fetch pages from www.dmv.ca.gov at that point. The solution was to show the uncrawled link when we had a high level of confidence that it was the correct link.
You are unlikely to see this page from your search result except for the site: query that you did. Otherwise somebody would have to search for [CHINESE] Hey nighthawk or some portion thereof.
摘自公开归档,保留原文语言,版式经整理,外部媒体与邮箱地址已移除。